Cheat
xmllint XML check and query
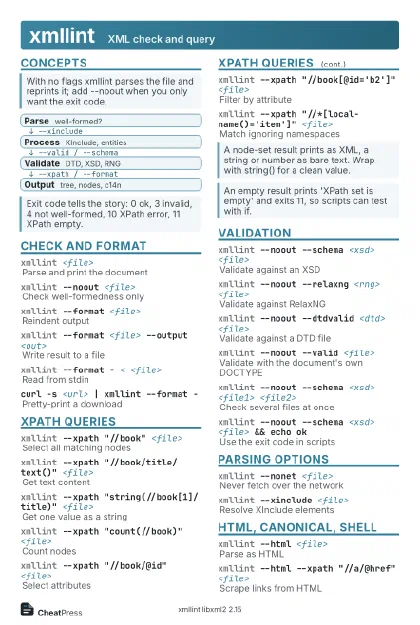 Light · Postcard
102 × 152 mm · PDF
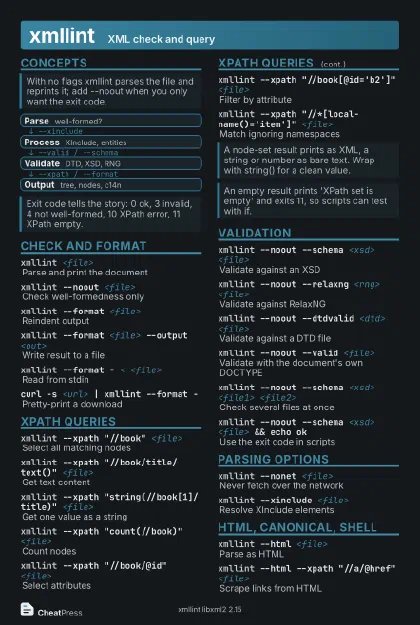 Dark · Postcard
102 × 152 mm · PDF
 Ink saver · Postcard
102 × 152 mm · PDF
 Light · A4 landscape
297 × 210 mm · PDF
 Dark · A4 landscape
297 × 210 mm · PDF
 Ink saver · A4 landscape
297 × 210 mm · PDF
 Light · A3 landscape
420 × 297 mm · PDF
 Dark · A3 landscape
420 × 297 mm · PDF
 Ink saver · A3 landscape
420 × 297 mm · PDF
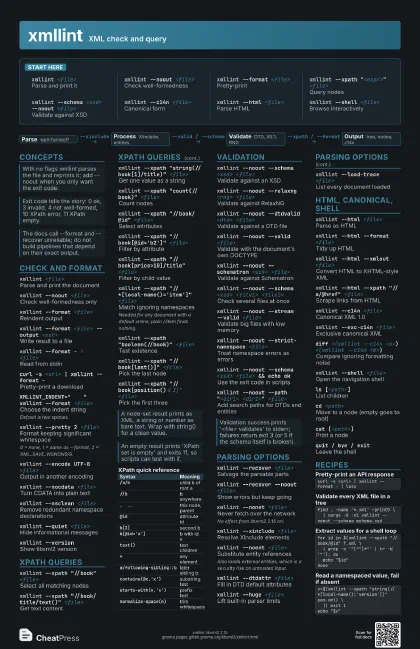
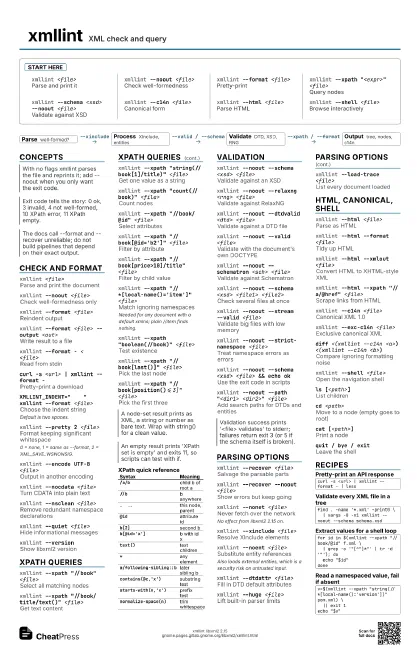
Start here
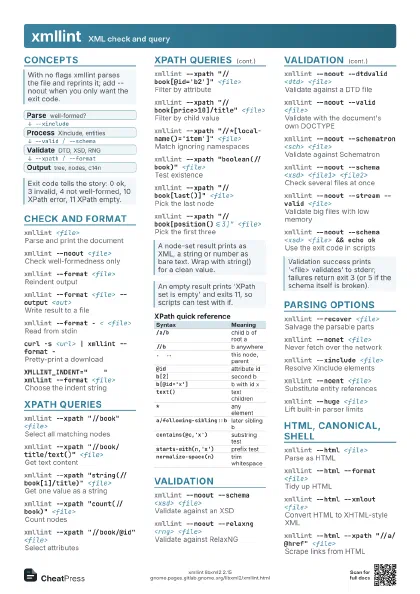
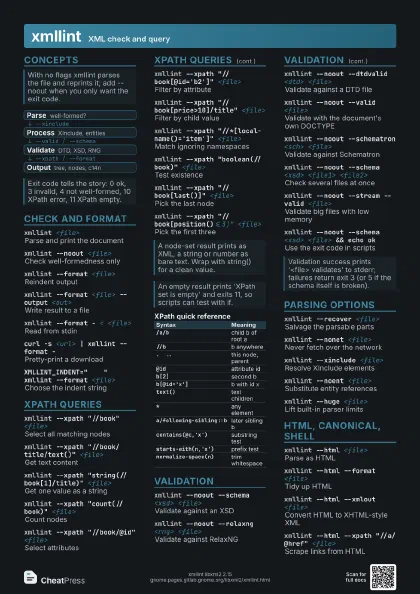
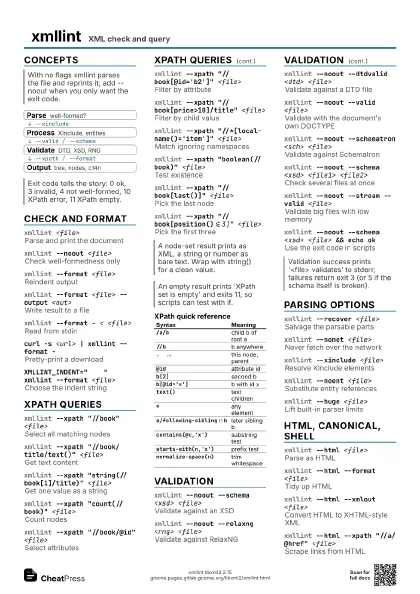
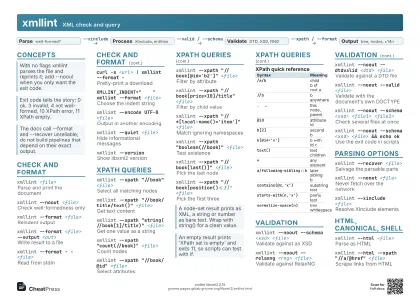
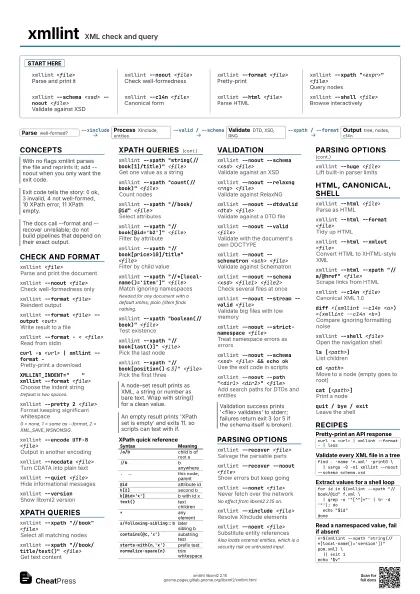
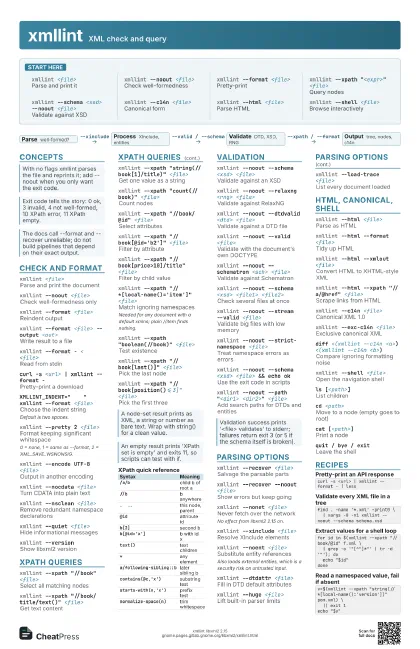
xmllint <file>
Parse and print it
xmllint --noout <file>
Check well-formedness
xmllint --format <file>
Pretty-print
xmllint --xpath "<expr>" <file>
Query nodes
xmllint --schema <xsd> --noout <file>
Validate against XSD
xmllint --c14n <file>
Canonical form
xmllint --html <file>
Parse HTML
xmllint --shell <file>
Browse interactively
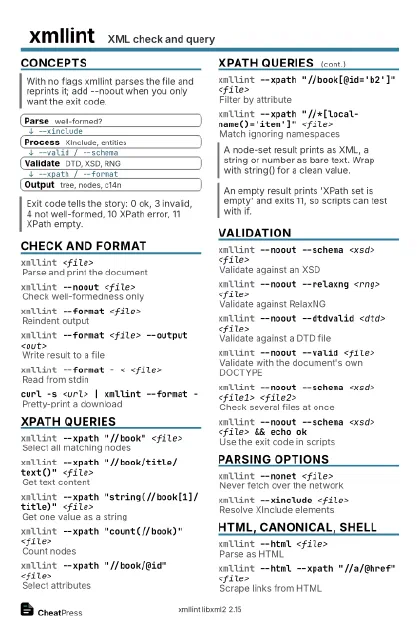
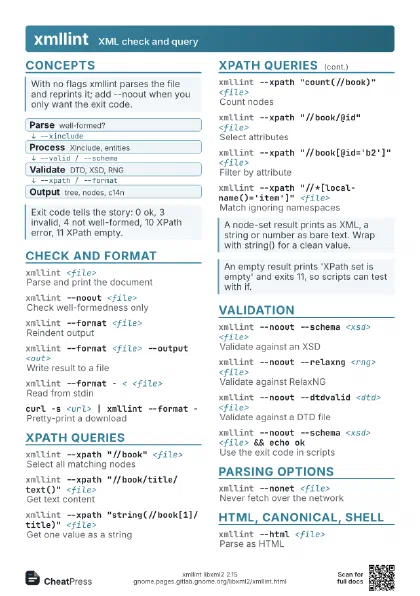
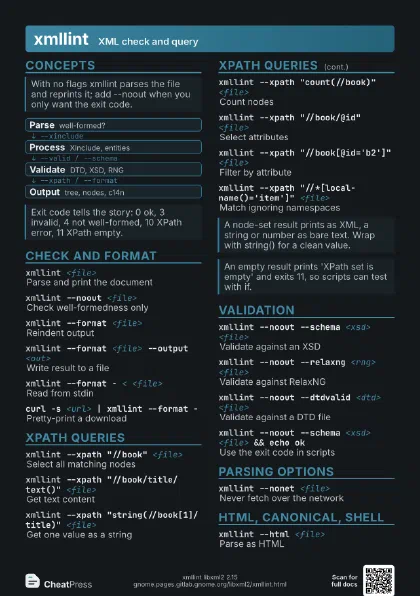
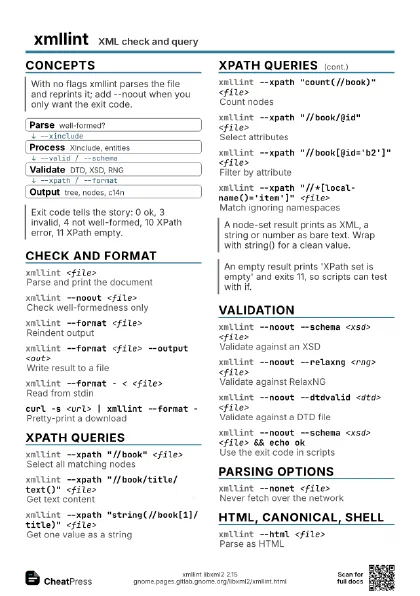
Concepts
- Parse well-formed?
- Process XInclude, entities
- Validate DTD, XSD, RNG
- Output tree, nodes, c14n
Check and format
xmllint <file>
Parse and print the document
xmllint --noout <file>
Check well-formedness only
xmllint --format <file>
Reindent output
xmllint --format <file> --output <out>
Write result to a file
xmllint --format - < <file>
Read from stdin
curl -s <url> | xmllint --format -
Pretty-print a download
XMLLINT_INDENT=" " xmllint --format
                    <file>
Choose the indent string
Default is two spaces.
xmllint --pretty 2 <file>
Format keeping significant whitespace
0 = none, 1 = same as --format, 2 = XML_SAVE_WSNONSIG.
xmllint --encode UTF-8 <file>
Output in another encoding
xmllint --nocdata <file>
Turn CDATA into plain text
xmllint --nsclean <file>
Remove redundant namespace declarations
xmllint --quiet <file>
Hide informational messages
xmllint --version
Show libxml2 version
XPath queries
xmllint --xpath "//book" <file>
Select all matching nodes
xmllint --xpath "//book/title/text()"
                    <file>
Get text content
xmllint --xpath "string(//book[1]/title)"
                    <file>
Get one value as a string
xmllint --xpath "count(//book)" <file>
Count nodes
xmllint --xpath "//book/@id" <file>
Select attributes
xmllint --xpath "//book[@id='b2']"
                    <file>
Filter by attribute
xmllint --xpath "//book[price>10]/title"
                    <file>
Filter by child value
xmllint --xpath "//*[local-name()='item']"
                    <file>
Match ignoring namespaces
Needed for any document with a default xmlns; plain //item
finds nothing.
xmllint --xpath "boolean(//book)"
                    <file>
Test existence
xmllint --xpath "//book[last()]" <file>
Pick the last node
xmllint --xpath "//book[position()<=3]"
                    <file>
Pick the first three
xmllint --xpath "//a | //b" <file>
Union of two selections
xmllint --xpath "concat(//a, '-', //b)"
                    <file>
Combine values
xmllint --xpath0 "<expr>" <file>
NUL-separated results
Listed in the synopsis but undocumented; test with your build
before relying on it.
| Syntax | Meaning |
|---|---|
/a/b |
child b of root a |
//b |
b anywhere |
. .. |
this node, parent |
@id |
attribute id |
b[2] |
second b |
b[@id='x'] |
b with id x |
text() |
text children |
* |
any element |
a/following-sibling::b |
later sibling b |
contains(@c,'x') |
substring test |
starts-with(n,'x') |
prefix test |
normalize-space(n) |
trim whitespace |
Validation
xmllint --noout --schema <xsd> <file>
Validate against an XSD
xmllint --noout --relaxng <rng> <file>
Validate against RelaxNG
xmllint --noout --dtdvalid <dtd> <file>
Validate against a DTD file
xmllint --noout --valid <file>
Validate with the document's own DOCTYPE
xmllint --noout --schematron <sch> <file>
Validate against Schematron
xmllint --noout --schema <xsd> <file1>
                    <file2>
Check several files at once
xmllint --noout --stream --valid <file>
Validate big files with low memory
xmllint --noout --strict-namespace <file>
Treat namespace errors as errors
xmllint --noout --schema <xsd> <file>
                    && echo ok
Use the exit code in scripts
xmllint --noout --path "<dir1> <dir2>"
                    <file>
Add search paths for DTDs and entities
Parsing options
xmllint --recover <file>
Salvage the parsable parts
xmllint --recover --noout <file>
Show errors but keep going
xmllint --nonet <file>
Never fetch over the network
No effect from libxml2 2.15 on.
xmllint --xinclude <file>
Resolve XInclude elements
xmllint --noent <file>
Substitute entity references
Also loads external entities, which is a security risk on
untrusted input.
xmllint --dtdattr <file>
Fill in DTD default attributes
xmllint --huge <file>
Lift built-in parser limits
xmllint --max-ampl <n> <file>
Entity expansion limit
Guards against billion-laughs documents; default is 5.
xmllint --load-trace <file>
List every document loaded
HTML, canonical, shell
xmllint --html <file>
Parse as HTML
xmllint --html --format <file>
Tidy up HTML
xmllint --html --xmlout <file>
Convert HTML to XHTML-style XML
xmllint --html --xpath "//a/@href"
                    <file>
Scrape links from HTML
xmllint --html --noout <file> 2>&1
Show HTML parse errors
xmllint --c14n <file>
Canonical XML 1.0
xmllint --exc-c14n <file>
Exclusive canonical XML
diff <(xmllint --c14n <a>) <(xmllint --c14n
                    <b>)
Compare ignoring formatting noise
xmllint --shell <file>
Open the navigation shell
ls [<path>]
List children
cd <path>Move to a node (empty goes to root)
cat [<path>]
Print a node
du <path>Show subtree structure
validateCheck the document
write <file>
Save the current node
save [<file>]
Save the whole document
quit / bye / exit
Leave the shell
Recipes
curl -s <url> | xmllint --format - | lessfind . -name '*.xml' -print0 \ | xargs -0 -n1 xmllint --noout --schema schema.xsdfor id in $(xmllint --xpath "//book/@id" f.xml \ | grep -o '"[^"]*"' | tr -d '"'); do echo "$id"donev=$(xmllint --xpath "string(//*[local-name()='version'])" pom.xml) \ || exit 1echo "$v"