Cheat
SQL Query language
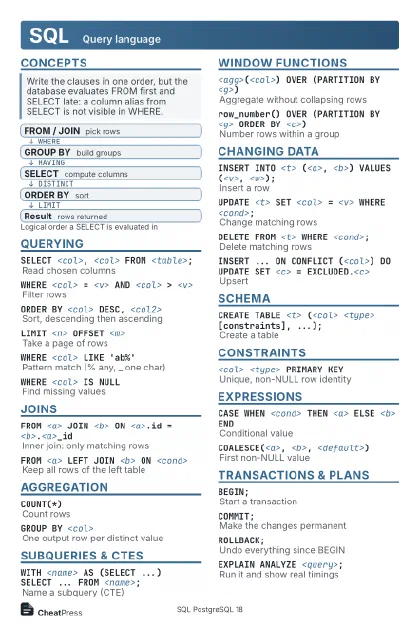 Light · Postcard
102 × 152 mm · PDF
 Dark · Postcard
102 × 152 mm · PDF
 Ink saver · Postcard
102 × 152 mm · PDF
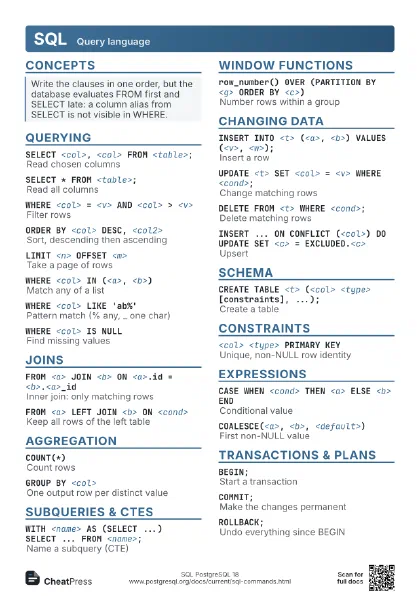
 Light · A4 landscape
297 × 210 mm · PDF
 Dark · A4 landscape
297 × 210 mm · PDF
 Ink saver · A4 landscape
297 × 210 mm · PDF
 Light · A3 landscape
420 × 297 mm · PDF
 Dark · A3 landscape
420 × 297 mm · PDF
 Ink saver · A3 landscape
420 × 297 mm · PDF
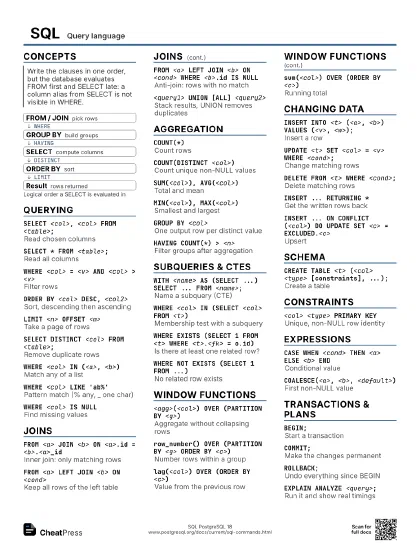
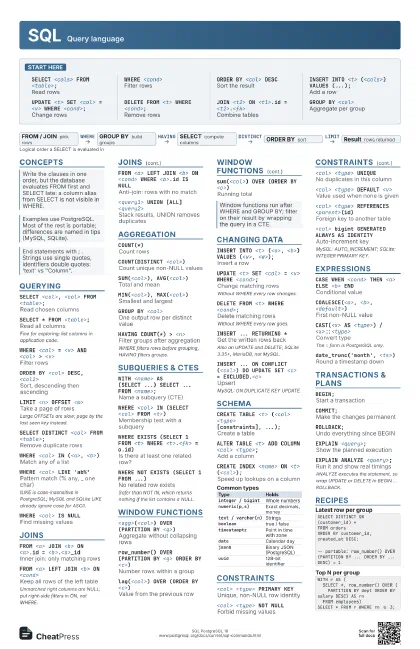
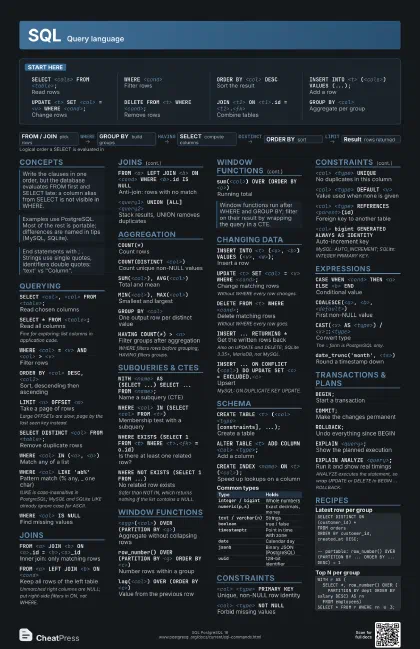
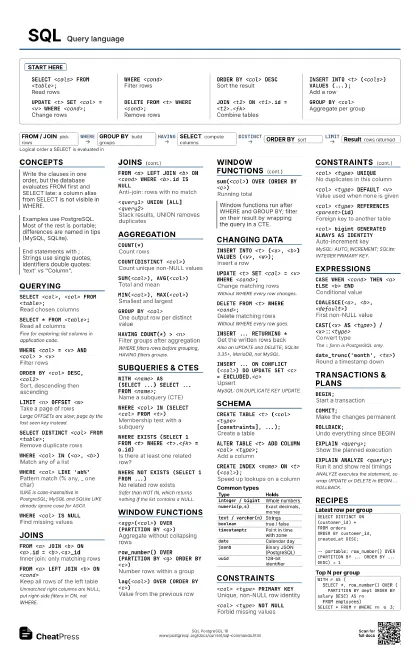
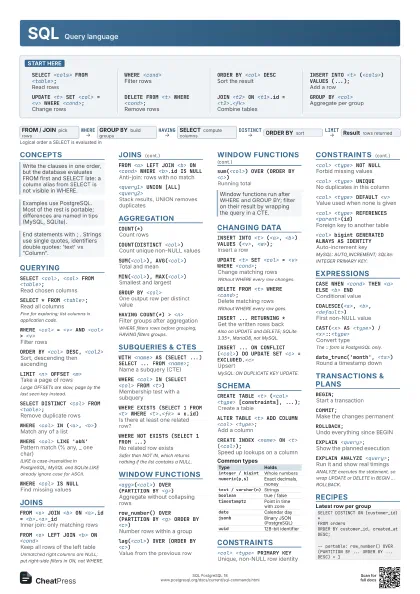
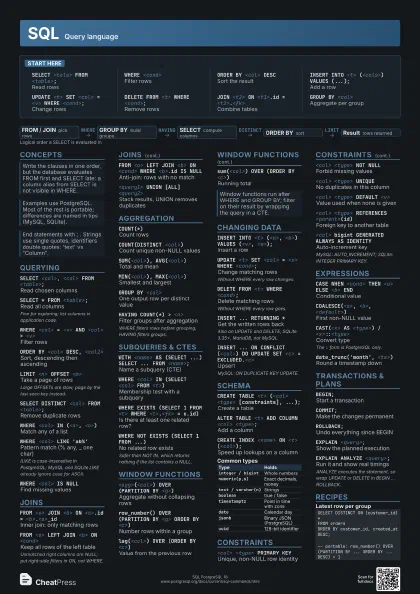
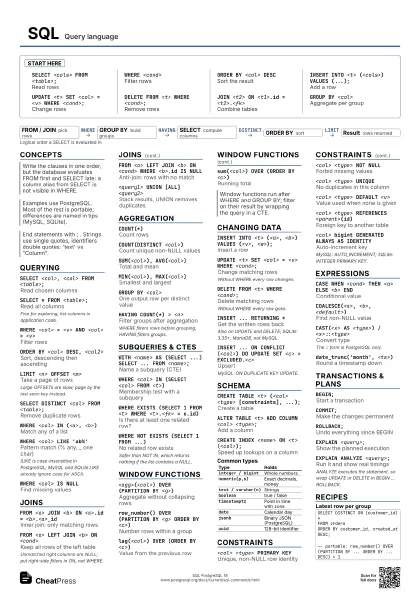
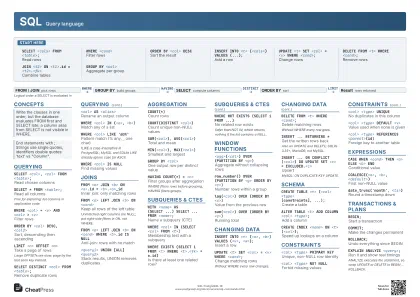
Start here
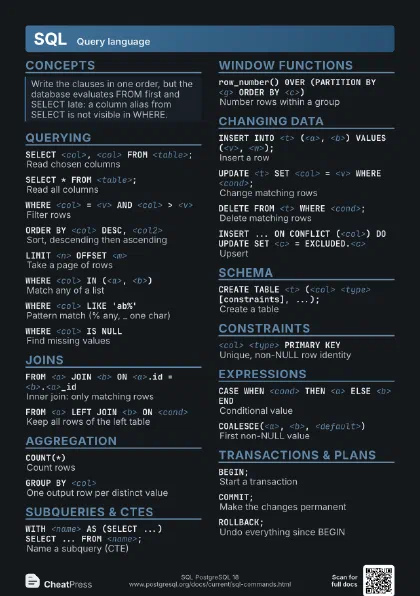
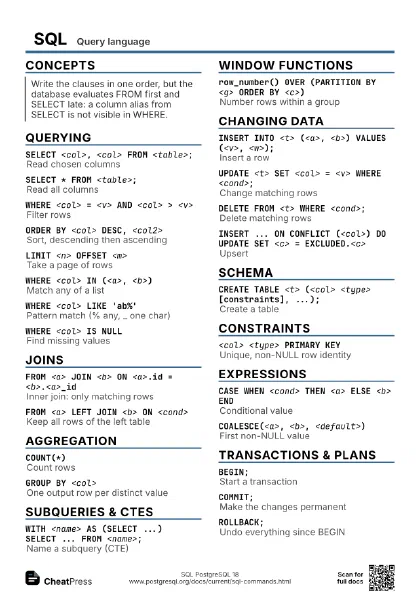
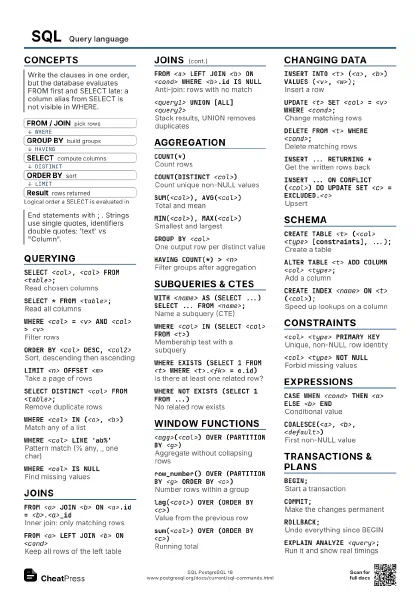
SELECT <cols> FROM <table>;
Read rows
WHERE <cond>
Filter rows
ORDER BY <col> DESC
Sort the result
INSERT INTO <t> (<cols>) VALUES (...);
Add a row
UPDATE <t> SET <col> = <v> WHERE
                    <cond>;
Change rows
DELETE FROM <t> WHERE <cond>;
Remove rows
JOIN <t2> ON <t1>.id =
                    <t2>.<fk>
Combine tables
GROUP BY <col>
Aggregate per group
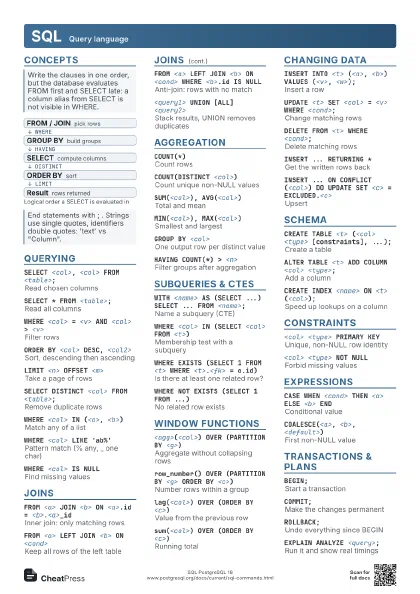
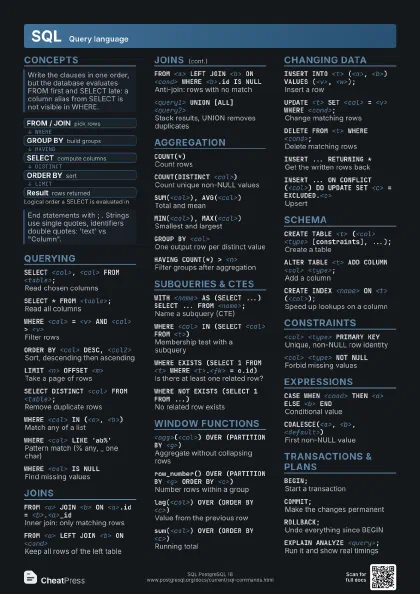
Concepts
- FROM / JOIN pick rows
- GROUP BY build groups
- SELECT compute columns
- ORDER BY sort
- Result rows returned
Querying
SELECT <col>, <col> FROM <table>;
Read chosen columns
SELECT * FROM <table>;
Read all columns
Fine for exploring; list columns in application code.
WHERE <col> = <v> AND <col> >
                    <v>
Filter rows
ORDER BY <col> DESC, <col2>
Sort, descending then ascending
LIMIT <n> OFFSET <m>
Take a page of rows
Large OFFSETs are slow; page by the last seen key instead.
SELECT DISTINCT <col> FROM <table>;
Remove duplicate rows
<col> AS <alias>
Rename an output column
WHERE <col> IN (<a>, <b>)
Match any of a list
WHERE <col> BETWEEN <a> AND <b>
Inclusive range
WHERE <col> LIKE 'ab%'
Pattern match (% any, _ one char)
ILIKE is case-insensitive in PostgreSQL; MySQL and SQLite LIKE
already ignore case for ASCII.
WHERE <col> IS NULL
Find missing values
SELECT DISTINCT ON (<col>) * FROM <t> ORDER BY
                    <col>, <ts> DESC;
First row per key (PostgreSQL)
Joins
FROM <a> JOIN <b> ON <a>.id =
                    <b>.<a>_id
Inner join: only matching rows
FROM <a> LEFT JOIN <b> ON <cond>
Keep all rows of the left table
Unmatched right columns are NULL; put right-side filters in
ON, not WHERE.
FROM <a> FULL JOIN <b> ON <cond>
Keep unmatched rows from both
MySQL has no FULL JOIN; SQLite supports it since 3.39.
FROM <a> JOIN <b> USING (<col>)
Join on same-named column
FROM <t> AS x JOIN <t> AS y ON x.<parent>
                    = y.id
Self join with aliases
FROM <a> LEFT JOIN <b> ON <cond> WHERE
                    <b>.id IS NULL
Anti-join: rows with no match
<query1> UNION [ALL] <query2>
Stack results, UNION removes duplicates
<query1> EXCEPT <query2>
Rows only in the first
Called MINUS in Oracle.
Aggregation
COUNT(*)Count rows
COUNT(DISTINCT <col>)
Count unique non-NULL values
SUM(<col>), AVG(<col>)
Total and mean
MIN(<col>), MAX(<col>)
Smallest and largest
GROUP BY <col>
One output row per distinct value
HAVING COUNT(*) > <n>
Filter groups after aggregation
WHERE filters rows before grouping, HAVING filters groups.
COUNT(*) FILTER (WHERE <cond>)
Conditional aggregate
MySQL and older SQLite: SUM(CASE WHEN ... THEN 1 ELSE 0 END).
string_agg(<col>, ', ')
Join values into one string
MySQL: GROUP_CONCAT; SQLite: group_concat.
Subqueries & CTEs
WITH <name> AS (SELECT ...) SELECT ... FROM
                    <name>;
Name a subquery (CTE)
WHERE <col> IN (SELECT <col> FROM
                    <t>)
Membership test with a subquery
WHERE EXISTS (SELECT 1 FROM <t> WHERE
                    <t>.<fk> = o.id)
Is there at least one related row?
WHERE NOT EXISTS (SELECT 1 FROM ...)
No related row exists
Safer than NOT IN, which returns nothing if the list contains
a NULL.
SELECT (SELECT max(<col>) FROM <t>) AS m
Scalar subquery
FROM (SELECT ...) AS s
Derived table: needs an alias
WITH RECURSIVE <n>(...) AS (<base> UNION ALL
                    <step>)
Walk trees and graphs
Window functions
<agg>(<col>) OVER (PARTITION BY
                    <g>)
Aggregate without collapsing rows
row_number() OVER (PARTITION BY <g> ORDER BY
                    <c>)
Number rows within a group
rank() OVER (ORDER BY <c> DESC)
Rank with gaps on ties
lag(<col>) OVER (ORDER BY <c>)
Value from the previous row
sum(<col>) OVER (ORDER BY <c>)
Running total
avg(<col>) OVER (ORDER BY <c> ROWS 6
                    PRECEDING)
Moving average over 7 rows
Changing data
INSERT INTO <t> (<a>, <b>) VALUES
                    (<v>, <w>);
Insert a row
INSERT INTO <t> (<a>) VALUES (<v>),
                    (<w>);
Insert several rows
INSERT INTO <t> (<a>) SELECT <a> FROM
                    <src>;
Insert from a query
UPDATE <t> SET <col> = <v> WHERE
                    <cond>;
Change matching rows
Without WHERE every row changes.
DELETE FROM <t> WHERE <cond>;
Delete matching rows
Without WHERE every row goes.
INSERT ... RETURNING *
Get the written rows back
Also on UPDATE and DELETE; SQLite 3.35+, MariaDB, not
MySQL.
INSERT ... ON CONFLICT (<col>) DO UPDATE SET
                    <c> = EXCLUDED.<c>
Upsert
MySQL: ON DUPLICATE KEY UPDATE.
INSERT ... ON CONFLICT DO NOTHING
Skip rows that already exist
UPDATE <t> SET <c> = s.<c> FROM <s>
                    WHERE <t>.id = s.id
Update from another table (PostgreSQL)
Schema
CREATE TABLE <t> (<col> <type>
                    [constraints], ...);
Create a table
DROP TABLE [IF EXISTS] <t>;
Remove a table
ALTER TABLE <t> ADD COLUMN <col>
                    <type>;
Add a column
ALTER TABLE <t> DROP COLUMN <col>;
Drop a column
ALTER TABLE <t> ALTER COLUMN <col> TYPE
                    <type>;
Change a column type (PostgreSQL)
ALTER TABLE <t> RENAME TO <new>;
Rename a table
CREATE INDEX <name> ON <t> (<col>);
Speed up lookups on a column
CREATE UNIQUE INDEX <name> ON <t>
                    (<col>);
Index that also enforces uniqueness
CREATE VIEW <v> AS SELECT ...;
Save a query as a virtual table
| Type | Holds |
|---|---|
integer / bigint |
Whole numbers |
numeric(p,s) |
Exact decimals, money |
text / varchar(n) |
Strings |
boolean |
true / false |
timestamptz |
Point in time with zone |
date |
Calendar day |
jsonb |
Binary JSON (PostgreSQL) |
uuid |
128-bit identifier |
Constraints
<col> <type> PRIMARY KEY
Unique, non-NULL row identity
<col> <type> NOT NULL
Forbid missing values
<col> <type> UNIQUE
No duplicates in this column
<col> <type> DEFAULT <v>
Value used when none is given
<col> <type> REFERENCES
                    <parent>(id)
Foreign key to another table
... ON DELETE CASCADE
Delete child rows with the parent
CHECK (<col> > 0)
Reject rows failing a condition
<col> bigint GENERATED ALWAYS AS IDENTITY
Auto-increment key
MySQL: AUTO_INCREMENT; SQLite: INTEGER PRIMARY KEY.
Expressions
CASE WHEN <cond> THEN <a> ELSE <b>
                    END
Conditional value
COALESCE(<a>, <b>, <default>)
First non-NULL value
NULLIF(<a>, <b>)
NULL when equal; avoids divide by zero
CAST(<x> AS <type>) /
                    <x>::<type>
Convert type
The :: form is PostgreSQL only.
<a> || <b>
Concatenate strings
lower(<s>), upper(<s>), length(<s>)
Basic string functions
now(), current_date
Current time and date
date_trunc('month', <ts>)
Round a timestamp down
<ts> + interval '7 days'
Date arithmetic
Transactions & plans
BEGIN;Start a transaction
COMMIT;Make the changes permanent
ROLLBACK;Undo everything since BEGIN
EXPLAIN <query>;
Show the planned execution
EXPLAIN ANALYZE <query>;
Run it and show real timings
ANALYZE executes the statement, so wrap UPDATE or DELETE in
BEGIN ... ROLLBACK.
Recipes
SELECT DISTINCT ON (customer_id) *FROM ordersORDER BY customer_id, created_at DESC;-- portable: row_number() OVER (PARTITION BY ... ORDER BY ... DESC) = 1WITH r AS ( SELECT *, row_number() OVER ( PARTITION BY dept ORDER BY salary DESC) AS rn FROM employees)SELECT * FROM r WHERE rn <= 3;INSERT INTO counters (name, n) VALUES ('hits', 1)ON CONFLICT (name) DO UPDATE SET n = counters.n + 1RETURNING *;